The AI Prototype Worked: Now Comes The Hard Part
The AI Prototype Worked: Now Comes The Hard Part
There is a moment in almost every AI project that feels magical.
You have spent a few days, maybe a few weeks, building something. You connect a model. You write a few prompts. You upload some documents. You build a simple interface.
And then it works.
The AI answers the question correctly.
It summarises the document.
It classifies the request.
It generates the report.
It calls the API.
It completes the workflow.
Everyone gets excited.
We have it.
And honestly, this is one of the things I love most about where we are with AI right now. The distance between having an idea and having something working in front of you has become ridiculously short.
You can build a chatbot in a day. You can build a RAG application over a weekend. You can connect an LLM to a database and suddenly you have something that looks like an intelligent analytics assistant. You can build an agent that calls APIs, completes tasks and produces something that feels remarkably close to a finished product.
But there is another distance that we don't talk about enough.
The distance between:
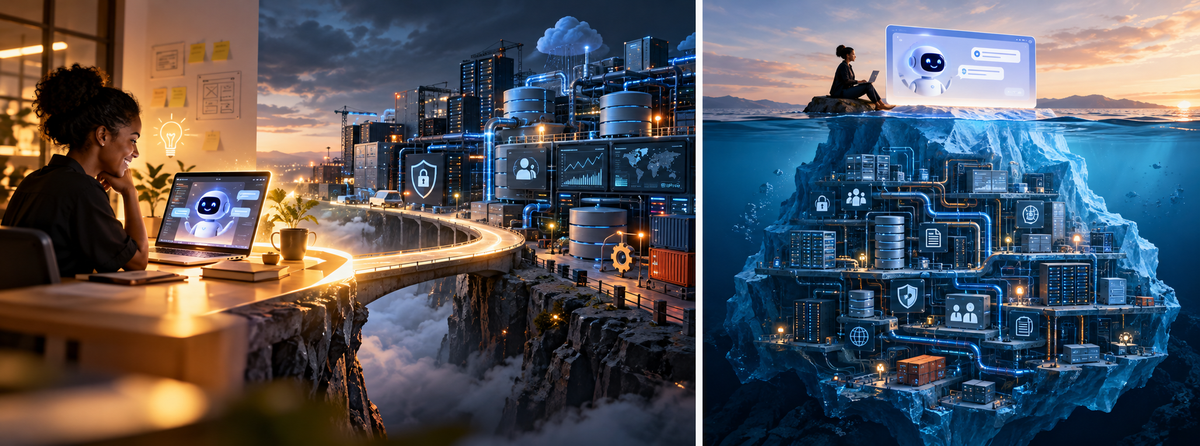
Something that works
and
Something you can trust in production.
That distance can be enormous.
And this is where the real work begins.
The demo is supposed to work
A prototype has one primary job.
It needs to answer:
Can this idea work?
That is a very different question from:
Can 50,000 people use this safely every day?
A prototype might run beautifully with one user and five documents. Production might need to handle thousands of users and millions of documents.
A prototype can have one carefully written prompt. Production needs to deal with prompt changes, model changes, evaluation, monitoring, failure handling and everything that happens when people use the system in ways you never expected.
And AI prototypes are particularly deceptive because they can look incredibly good.
Traditional software often fails loudly.
The button doesn't work.
The API returns a 500.
The application crashes.
You know something is wrong.
AI systems can be wrong while sounding completely confident.
That is a very different kind of problem.
"It answered correctly" is not an evaluation
This is probably one of the easiest traps to fall into.
You build the application.
You ask it ten questions.
It answers nine correctly.
Everyone is impressed.
We conclude that it works.
But what have we actually proven?
Maybe those were easy questions.
Maybe the answer was obvious in the documents.
Maybe the person testing the system already knew exactly how to phrase the question.
Maybe question number eleven would have exposed a fundamental problem.
This is where AI engineering becomes different from simply putting an AI feature inside an application.
At some point you have to move from:
It looks good
to:
We can measure how good it is.
You need test data. You need expected outcomes. You need some way of measuring whether your changes are making the system better or worse.
And that becomes surprisingly complicated because AI systems are not deterministic in the same way that traditional software is.
- You can improve the system prompt and suddenly classification gets worse.
- You can change the model and get answers that sound better but are less factual.
- You can improve retrieval quality and double your response time.
- You can add more context and watch your token costs explode.
- You can make the model more creative and suddenly it starts inventing things.
So the question is no longer simply:
Does it work?
The question becomes:
How well does it work, under which conditions, and how consistently?
The happy path is very seductive
The prototype normally shows the happy path.
Someone asks a reasonable question.
The right information is retrieved.
The model produces the right response.
Everyone claps.
Production is everything that happens around that happy path.
- What happens when the user asks a terrible question?
- What happens when the answer does not exist in the knowledge base?
- What happens when two documents contradict each other?
- What happens when one document is outdated?
- What happens when the retrieval system gives the model the wrong information?
- What happens when the model provider is down?
- What happens when a user deliberately tries to manipulate the model?
- What happens when someone uploads a document containing prompt injection instructions?
And then it gets even more interesting when the AI is no longer just answering questions.
Once the AI can do things, the risk changes
A chatbot giving the wrong answer is one thing.
An AI agent that can actually take actions is something completely different.
Maybe your prototype can create an account, issue a refund, update a CRM, query a database, send an email, approve a workflow or call an internal API.
That is exciting.
But now we need another conversation.
- What is the agent allowed to do?
- For whom?
- Under what circumstances?
- What needs human approval?
- What is the financial limit?
- What happens if the model misunderstands an instruction?
- Can somebody manipulate the model into calling a tool they should not have access to?
- Can the agent access another customer's data?
- Can you reconstruct exactly what happened afterwards?
These are no longer prompt engineering questions.
These are architecture, identity, security and governance questions.
The moment your AI can take action, you have effectively introduced another actor into your system.
That actor needs controls.
Then your RAG application meets real data
RAG demos are another perfect example.
Take ten PDFs.
Split them into chunks.
Create embeddings.
Put them in a vector database.
Ask a few questions.
Amazing.
Now production arrives.
Suddenly there are thousands of documents.
Then hundreds of thousands.
There are scanned PDFs, spreadsheets, old policies, new policies, duplicate files, badly formatted documents and information belonging to different customers.
Now the difficult questions are not about which embedding model you should use.
The difficult questions are about permissions.
- How do you ensure that the right person can retrieve the right information?
- How do you know which version of a policy is authoritative?
- How do you remove information when it is deleted at source?
- How do you guarantee that customer A never retrieves customer B's data?
- How do you re-index millions of documents without breaking the application?
- How do you know when retrieval quality starts getting worse?
That is where the prototype ends and engineering starts.
Then comes observability
One of my favourite questions in software engineering is:
How will we know when this thing is broken?
Because production systems will break.
That is not pessimism.
That is software.
With AI, this question becomes even more important because "broken" does not necessarily mean unavailable.
Your API can return 200 OK.
Your model can respond in under two seconds.
Your infrastructure dashboard can be completely green.
And the answer can still be terrible.
So observability in AI systems needs to go beyond CPU, memory, latency and error rates.
You need visibility into the actual behaviour of the AI.
- Are token costs increasing?
- Are tool calls failing?
- Are users rejecting answers?
- Is retrieval quality getting worse?
- Did a model update change the quality of responses?
- Are hallucinations increasing?
- Are requests being sent to fallback models?
- Which prompt version produced this answer?
That is a different type of observability.
Traditional monitoring tells you whether the system is alive.
AI monitoring needs to tell you whether the system is still useful.
Cost will eventually find you
AI prototypes have another wonderful ability.
They hide future bills.
When five people are testing your application, model cost looks irrelevant.
Then 10,000 users arrive.
Your application makes three LLM calls for every user request.
Your agent retries failed tasks.
Your RAG pipeline sends enormous context windows.
Someone changes the model because the more expensive one gives slightly better answers.
And suddenly:
"The AI costs almost nothing."
becomes:
"Why did the bill triple this month?"
Production forces you to understand the economics properly.
- What is the cost per transaction?
- What happens at one million transactions?
- Do all requests really need the most capable model?
- Can a cheaper model handle the simple cases?
- Can some tasks be done deterministically without AI at all?
- Can you cache anything?
- Do you really need to send the entire conversation history every single time?
The prototype proves the feature.
Production proves whether the economics make sense.
And then somebody mentions security
This is normally where the fun begins.
AI applications inherit all the normal security problems we already had in software.
- Authentication.
- Authorisation.
- Encryption.
- Networking.
- Secrets.
- Logging.
- Patching.
- Data protection.
- Backups.
- Incident response.
And then we add some new ones.
- Prompt injection.
- Sensitive data leakage.
- Insecure tool use.
- Over-permissioned agents.
- Untrusted model output.
- Third-party model providers.
- AI supply-chain risk.
If you are building something in healthcare, finance, government, legal services or any environment containing sensitive information, these questions get serious very quickly.
Suddenly the question is no longer:
Can the AI answer this?
It becomes:
- Should this information even be sent to the model?
- Where does it go?
- How long is it retained?
- Who can access it?
- Which region is processing it?
- Can it be used for training?
- How do we prove any of this to a customer, regulator or auditor?
Not quite as exciting as the demo.
Much more important.
Reliability becomes interesting when AI sits inside a workflow
Imagine an AI agent is one step in a twelve-step business process.
The agent fails.
Now what?
- Does the entire transaction fail?
- Does it retry?
- How many times?
- Can it accidentally execute the same operation twice?
- Can a human resume the process?
- Can the failed transaction be replayed?
- Do you know which model and which prompt produced the decision?
- What happens when your AI provider is unavailable?
- Does your entire business process stop because one external API went down?
These are not really AI problems.
They are engineering problems around an AI component.
And I think that distinction matters.
The model is only one part of the system
This is probably one of the biggest mindset shifts businesses need to make.
When people say:
"We are building an AI system."
the conversation often becomes completely focused on the model.
Which model?
Which prompt?
Which context window?
Which temperature?
But when you look at an actual production architecture, the model might be one relatively small component.
You still have users, APIs, databases, queues, caches, identity, storage, networking, monitoring, logging, CI/CD, security, backups, integrations and business logic.
Then somewhere inside all of that:
LLM call.
The model is enormously powerful.
But the system around the model is what turns it into a reliable product.
And the model will change
This is another thing I think we should assume from day one.
The model we use today is probably not the model we will use forever.
AI is moving far too quickly.
A better model will arrive.
A cheaper model will arrive.
Your provider might change pricing.
A client might require data to remain in a particular region.
You might need to move from a hosted model to a private model.
You might need to move from one provider to another.
If your entire application is tightly coupled to one provider and one model, that future change becomes painful.
Your business logic should not become OpenAI-shaped.
Or Gemini-shaped.
Or Claude-shaped.
The model is a dependency.
An extremely important dependency.
But still a dependency.
Good architecture should treat it that way.
Humans are still part of the architecture
AI has created this obsession with removing humans from every process.
And sometimes that absolutely makes sense.
There are processes that can and should be automated completely.
But in high-impact workflows, a human can still be one of the most important parts of the architecture.
AI can process 10,000 cases.
Maybe a person only needs to review 200.
AI can generate the recommendation.
A person approves the final action.
AI can classify the risk.
A human reviews anything above a threshold.
That is not a failure of AI.
That is good system design.
The goal does not always need to be:
Remove the human.
Sometimes the better question is:
Where does human judgement create the most value?
None of this means we should stop prototyping
Quite the opposite.
Prototype aggressively.
Build quickly.
Experiment.
Try different models.
Use AI coding tools.
Build the demo in three days if you can.
The cost of experimentation has collapsed and that is an incredible opportunity.
Businesses can test ideas that would previously have required enormous budgets.
Developers can explore different architectures before committing to one.
Teams can put working software in front of users much earlier.
That is a very good thing.
But understand what the prototype has actually proven.
It has proven:
This idea might be valuable.
It has not necessarily proven:
This system is ready.
Those are two completely different milestones.
Production is where engineering earns its money
The first part of an AI application can sometimes feel unbelievably easy.
The last part is where all the complexity hides.
Making the chatbot answer?
Easy.
Making sure it answers correctly?
Harder.
Making sure it answers correctly for thousands of users, against millions of records, with the correct permissions, at an acceptable cost, without leaking sensitive information, while surviving failures and giving you enough information to understand what happened when something goes wrong?
That is the job.
And this is why I think experienced engineers become even more valuable in the AI era, not less.
AI allows us to build increasingly sophisticated systems increasingly quickly.
Which also means we can create increasingly sophisticated problems increasingly quickly.
The technology has accelerated.
Our responsibility has not disappeared.
The prototype worked
And that is worth celebrating.
Seriously.
A working prototype means you have crossed one of the biggest barriers in product development.
You took something that existed in somebody's head and turned it into something real.
AI has made that process faster than I ever imagined when I started writing software.
But once everyone has finished celebrating the demo, another conversation needs to begin.
- How do we secure it?
- How do we test it?
- How do we measure it?
- How do we scale it?
- How do we monitor it?
- How do we control the cost?
- How do we protect the data?
- How do we recover when something breaks?
- How do we know when the AI is wrong?
- How do we stop it from doing something it should not do?
- How do we change models later without rebuilding the entire application?
- How do we operate this thing every single day?
Because the prototype proved that the idea can work.
Production is where we prove that we can trust it.